Overview
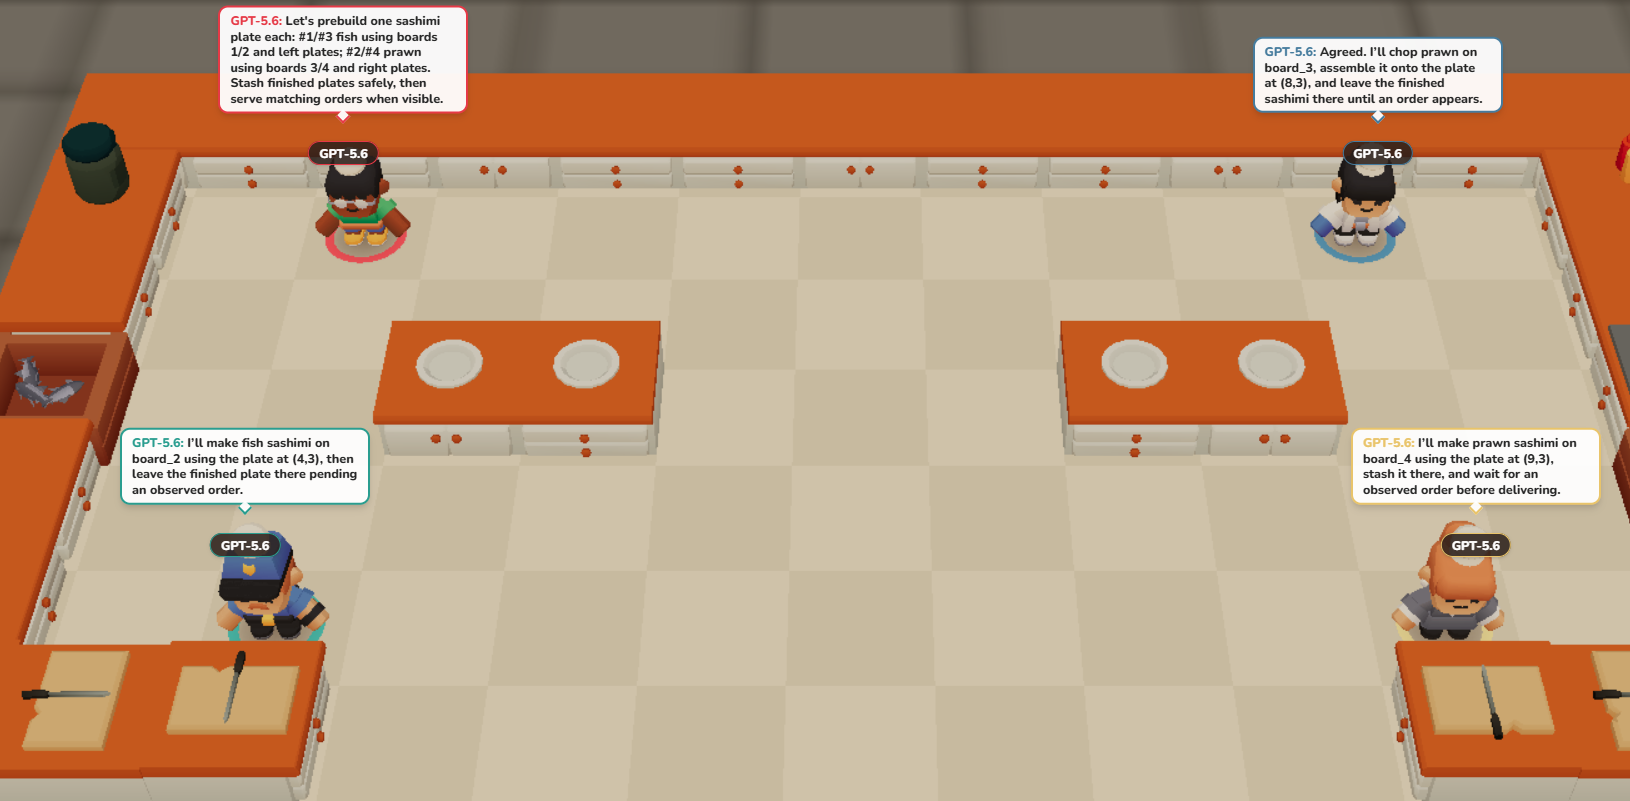
Overcooked is a collaborative cooking game for 4 players. This benchmark tests models on a variety of Overcooked levels. Each team consists of 4 separate agents using the same model, with their own plans and private notes. Scoring is based on the speed and accuracy of successful deliveries.
Leaderboard
| Model | |
|---|---|
GPT-6 AstraOpenAI | 58.54%-1.95 / +1.95 |
GPT-6.1 SolOpenAI | 56.50%-4.48 / +4.48 |
Claude Fable 5.1Anthropic | 52.78%-5.03 / +5.03 |
GPT-5.6 SolOpenAI | 43.51%-3.85 / +3.85 |
Claude Opus 5.5Anthropic | 42.33%-4.15 / +4.15 |
DeepSeek V4.1 FlashDeepSeek | 40.18%-3.05 / +3.05 |
Grok 4.7xAI | 38.63%-3.90 / +3.90 |
Claude Opus 5Anthropic | 37.34%-4.47 / +4.47 |
Gemini 3.7 FlashGoogle | 32.47%-4.63 / +4.63 |
Gemini 3.8 FlashGoogle | 27.64%-3.92 / +3.92 |
GPT-5.6 TerraOpenAI | 27.14%-3.06 / +3.06 |
GPT-5.4OpenAI | 26.17%-2.60 / +2.60 |
GLM-5.3Z.ai | 26.09%-4.37 / +4.37 |
Kimi K3Moonshot AI | 24.50%-4.79 / +4.79 |
Grok 4.6xAI | 24.32%-4.15 / +4.15 |
Gemini 3.1 Pro PreviewGoogle | 21.75%-3.92 / +3.92 |
DeepSeek V4 Pro 0813DeepSeek | 21.74%-4.22 / +4.22 |
Muse Spark 1.3Meta | 21.14%-4.79 / +4.79 |
Claude Sonnet 5Anthropic | 15.83%-4.85 / +4.85 |
GLM-5.3 FlashZ.ai | 13.10%-3.65 / +3.65 |
GPT-6 LunaOpenAI | 8.66%-3.17 / +3.17 |
Claude Sonnet 5.5Anthropic | 7.57%-2.31 / +2.31 |
GPT-5.6 LunaOpenAI | 5.63%-2.93 / +2.93 |

Purpose
In Overcooked, a finished dish depends on a series of steps in which some are parallelizable, and some are not. Ingredients must be prepared, cooked, combined with a clean plate, and delivered before a deadline.
Chefs share equipment, counters, and a limited supply of plates. Some levels have moving furniture, which adds periods when a handoff or crossing is not possible.
Two or more chefs can claim the same ingredient, block each other's route, or prepare food while nobody washes the plates needed to serve it.
Overcooked requires coordination in a changing environment, the ability to delegate and reassign tasks without a central leader, and spatial awareness in a 2d world.
It provides an effective way to test the capabilities of small agent swarms.
Harness
Agents are given several tools to play the game, such as: pickup, chop, deliver, place_counter. Movement and pathfinding are handled by the engine.
During the game, the simulation pauses every 60 ticks, and each agent can send one message to the others to coordinate. After that, they can plan their actions for the next segment. The game is then unpaused and the plans play out for the next 60 ticks. This repeats until the level timer runs out.
Scoring
Scores are expressed as a percentage of the maximum score that would be obtained with perfect play. Each score is calculated with a 95% confidence interval.